 Renmin University of China
Let it move.
TEST-TIME GEOMETRIC GUIDANCE
Steer a pretrained policy through geometry.
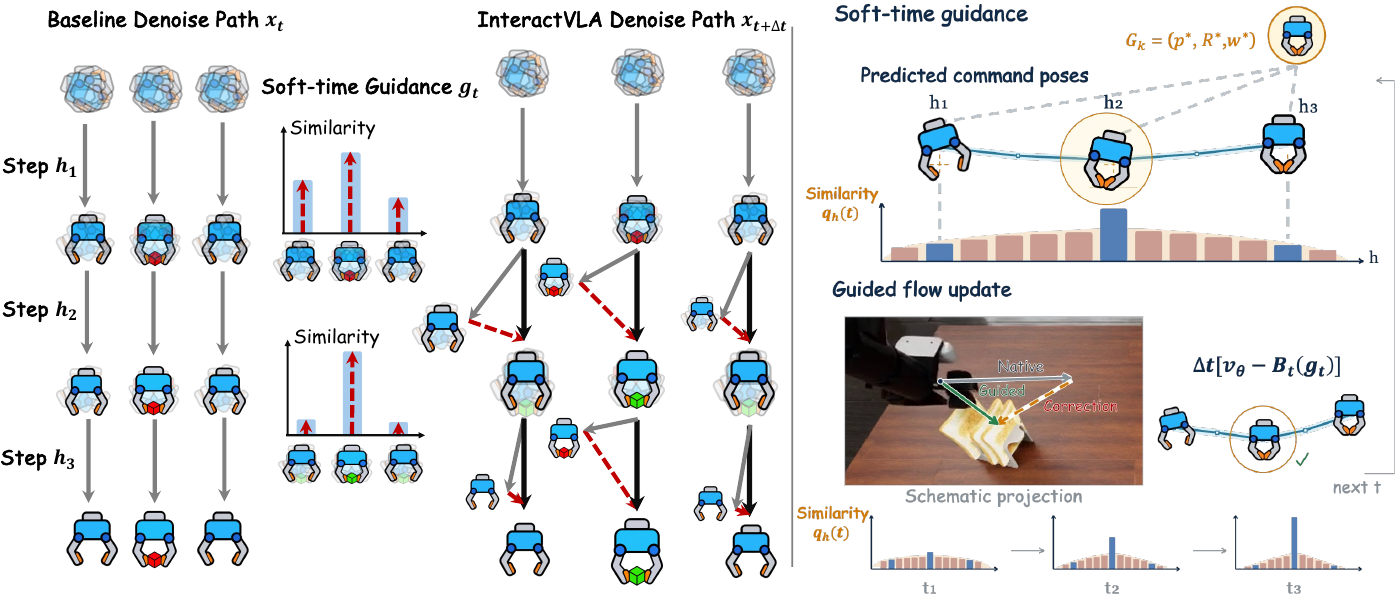
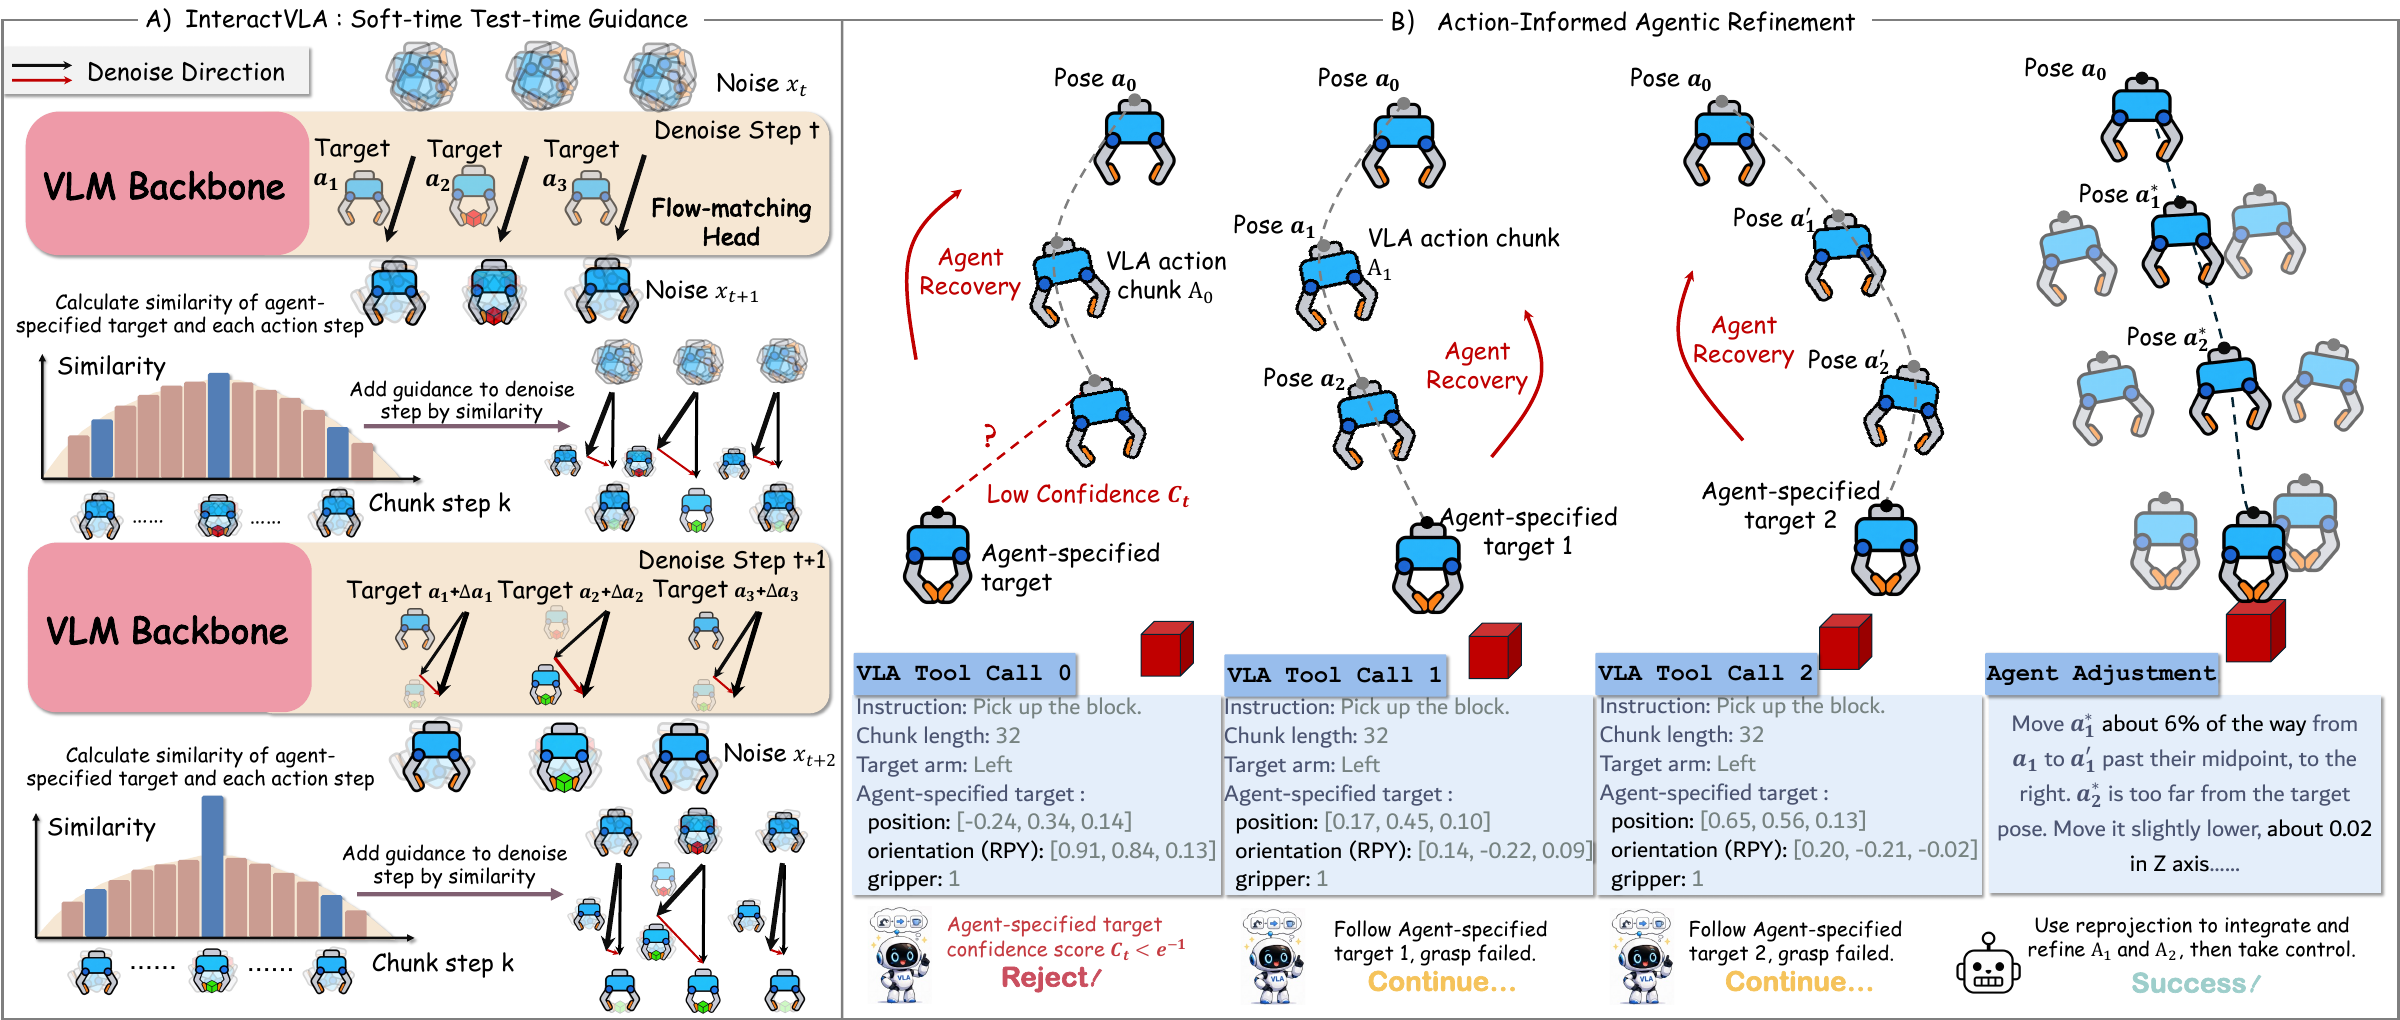
At each tool call, the agent supplies an end-effector target G = (p*, R*, w*): a position, an orientation, and a gripper state. The VLA keeps its learned motor behavior, while guidance redirects its action generation toward that target.
During flow denoising, we estimate the clean action chunk, map its native actions to command poses, and compute a complete-pose error at each execution step. Differentiating that objective through the current action expert produces a correction to the noisy action input. The policy weights stay frozen.
The guidance update
xt+Δt = sg[xt + Δt (vθ − Bt(gt))]
Bt scales and caps the correction and limits guidance to an interior time window. Each integration state is detached so gradients pass through the current expert only. For bimanual actions, pose errors are summed across effectors at a shared execution index.
Compatibility is Ct = exp[−max(rt/r0, dt/d0)]. After the first guided step, Ct < e−1 triggers early return.